Every kind of training data, held to a 99% standard
Annotation for images, video, medical scans, text, audio and multimodal data, plus the quality checks and data operations around it. One team, one QA process.
Illustrative samples. Client data is never shown.
Annotation
Labels for every kind of training data.
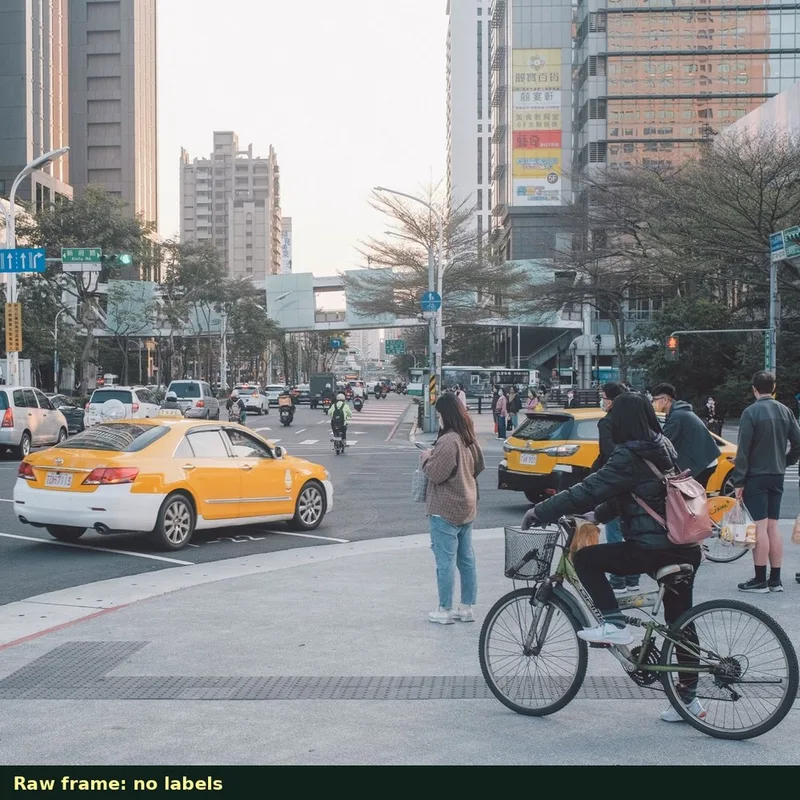
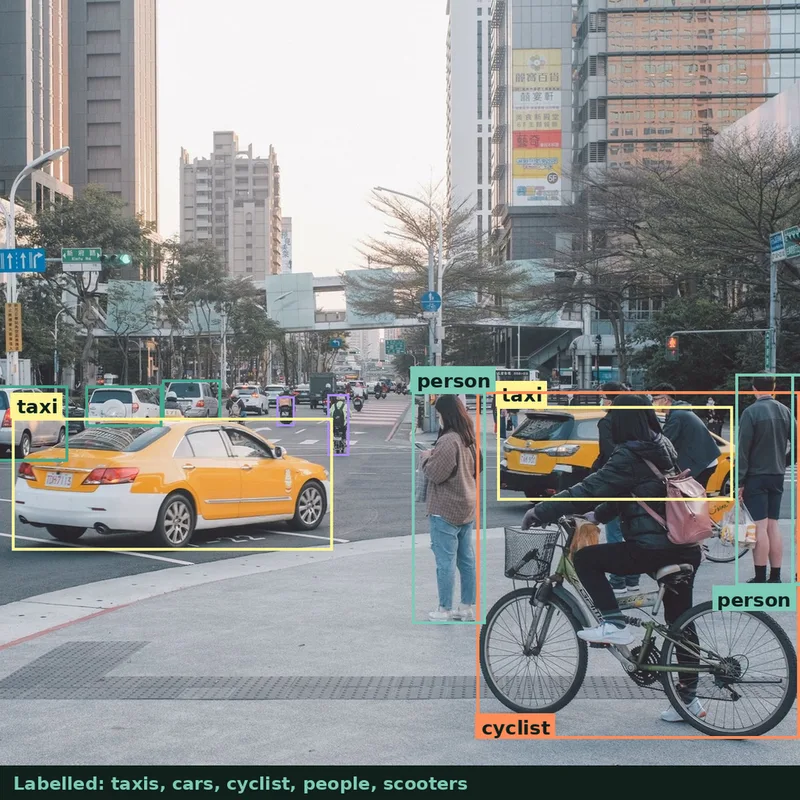
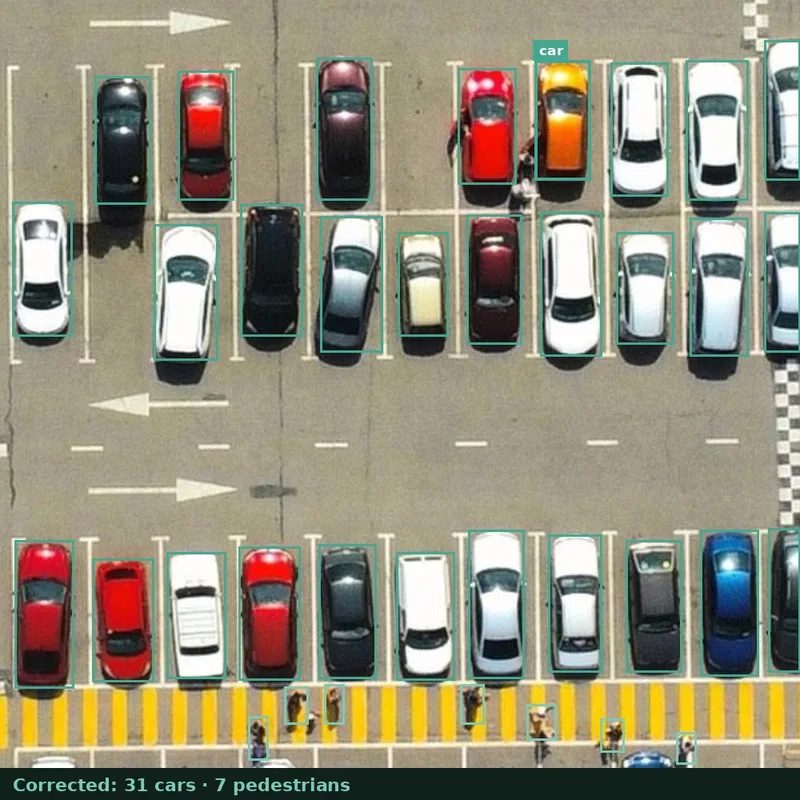
Image & video annotation
Precise labels for computer vision, checked twice before delivery.
- Bounding boxes
- 3D cuboids on images
- Polygons
- Semantic & instance segmentation
- Keypoints & pose
- Object tracking
- Event time-stamping
- Classification
Proven with Spiideo (30,000+ sports videos) and Katam (10,000+ forestry images)
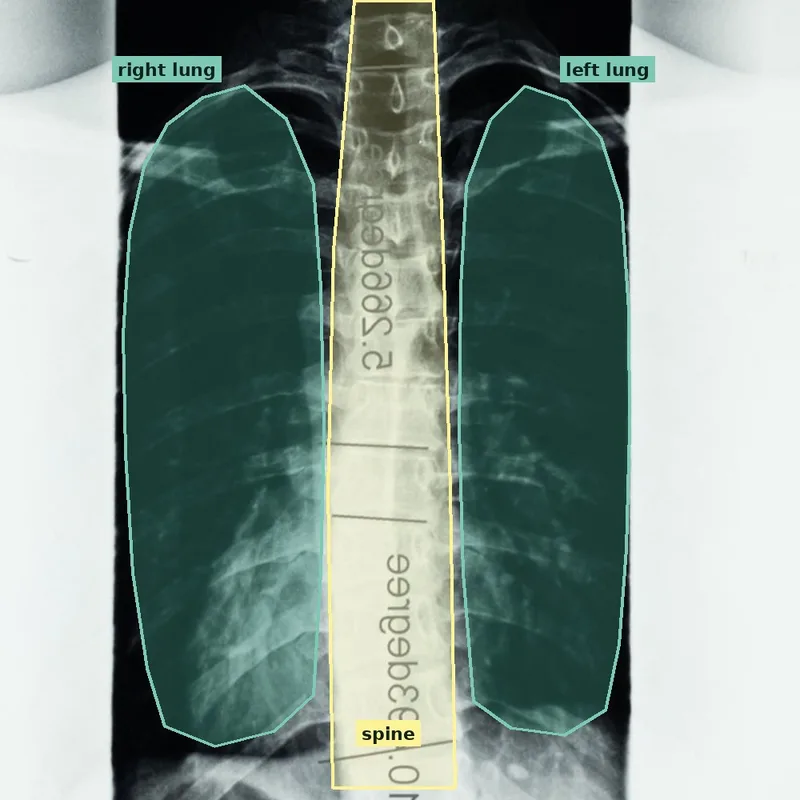
Medical imaging annotation
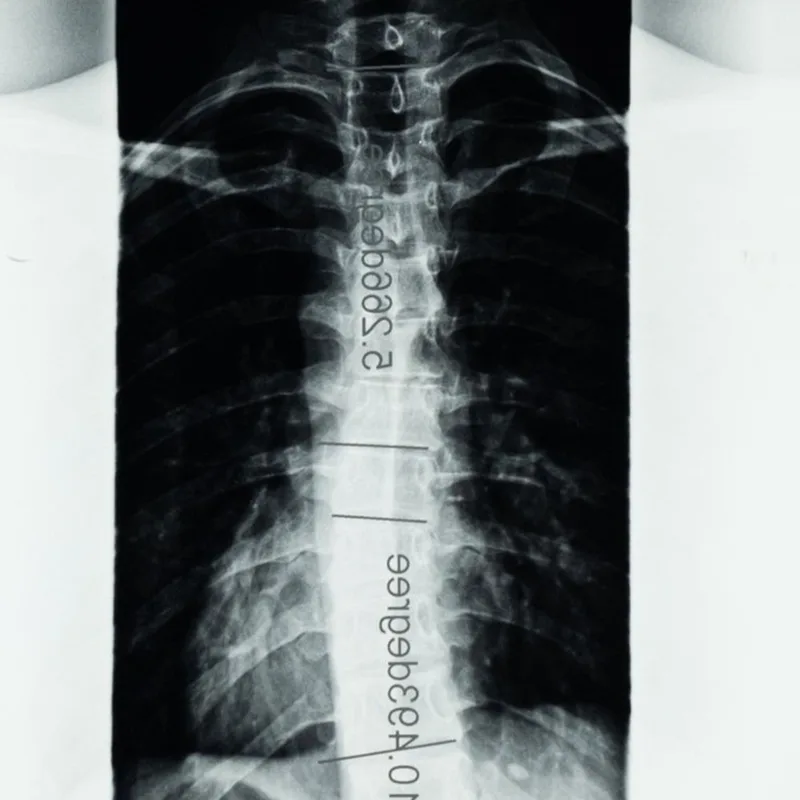
Organ and structure segmentation for diagnostic AI, reviewed in two layers.
- CT
- MRI
- X-ray
- Organ segmentation
- Structure & lesion outlining
- Cross-modality guidelines
Proven with SliceVault (10,000+ medical images)
Text & document annotation
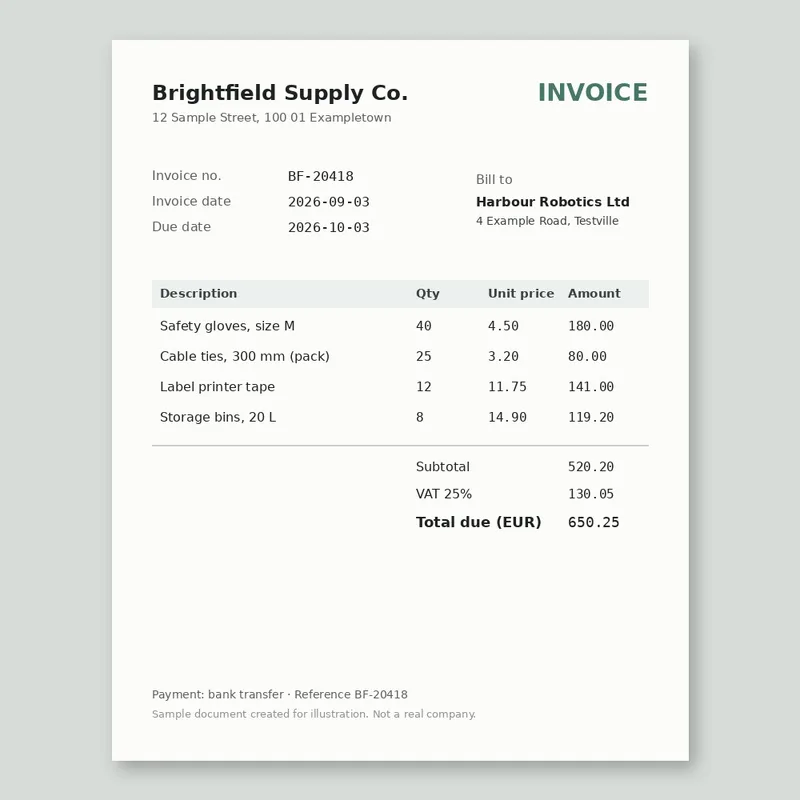
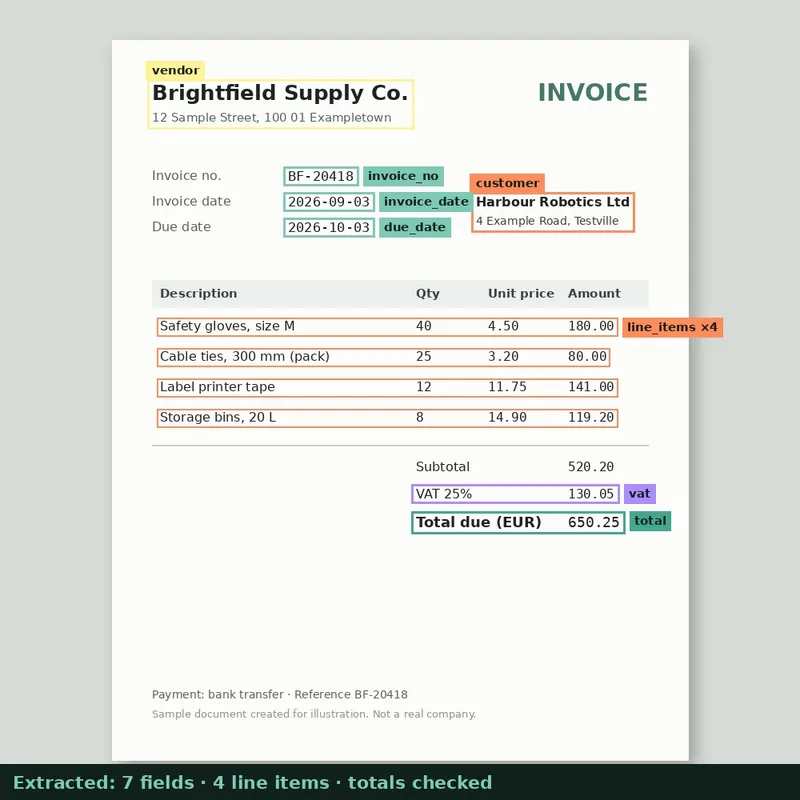
Structured labels for language and document AI, from sentiment and entities to fields pulled from scanned forms.
- Text classification
- Named entity recognition
- Sentiment analysis
- Document & OCR annotation
- Key-value extraction
- Invoices, forms & receipts
Audio & transcription
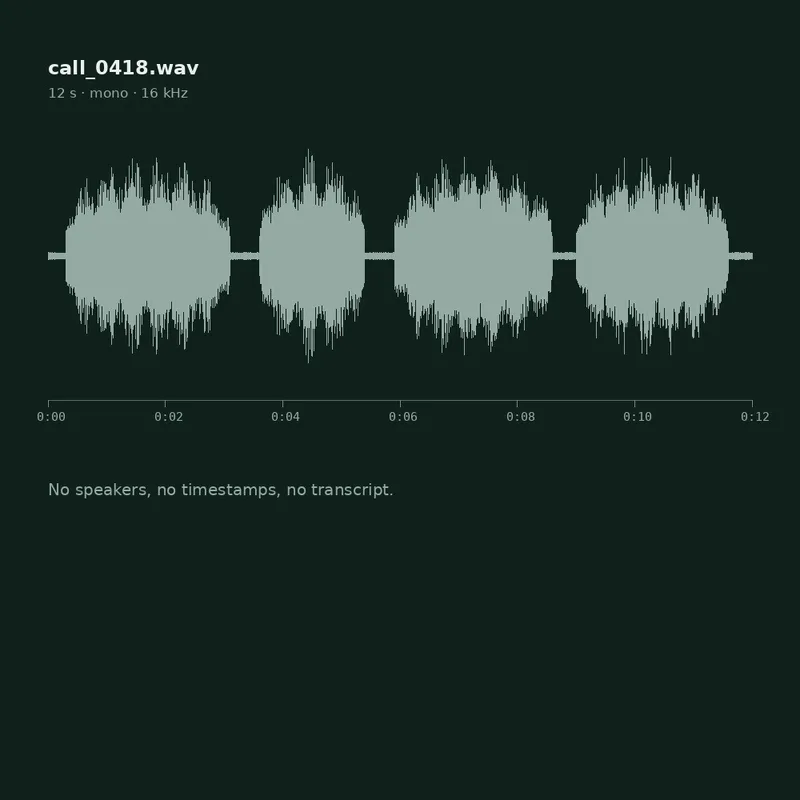
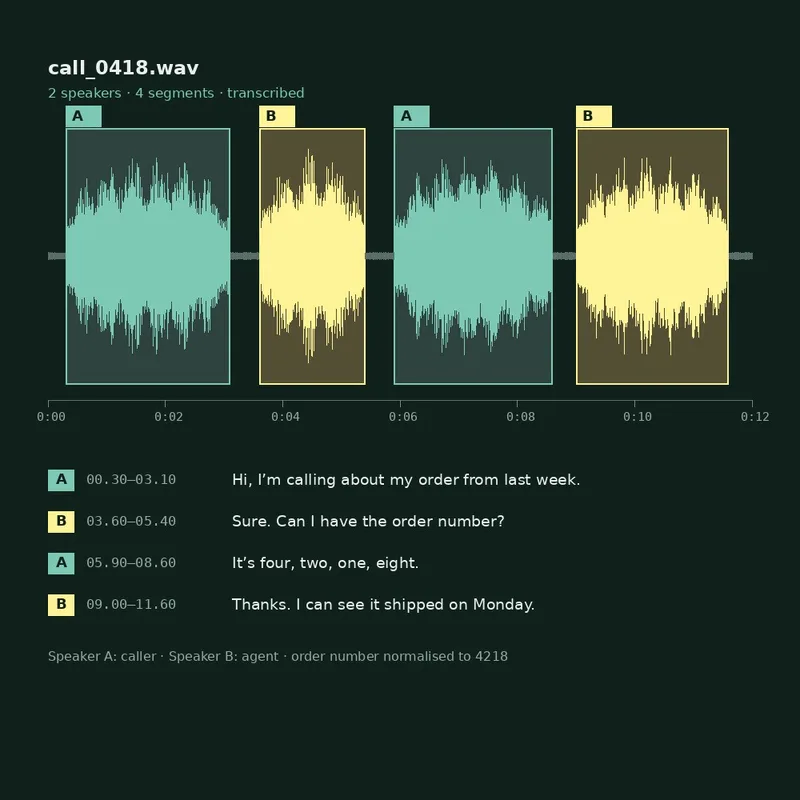
Accurate transcripts and audio labels for speech and sound models, with time-stamps and speaker tags.
- Speech-to-text transcription
- Time-stamping
- Speaker labelling
- Audio event tagging
- Transcript review
Multimodal annotation
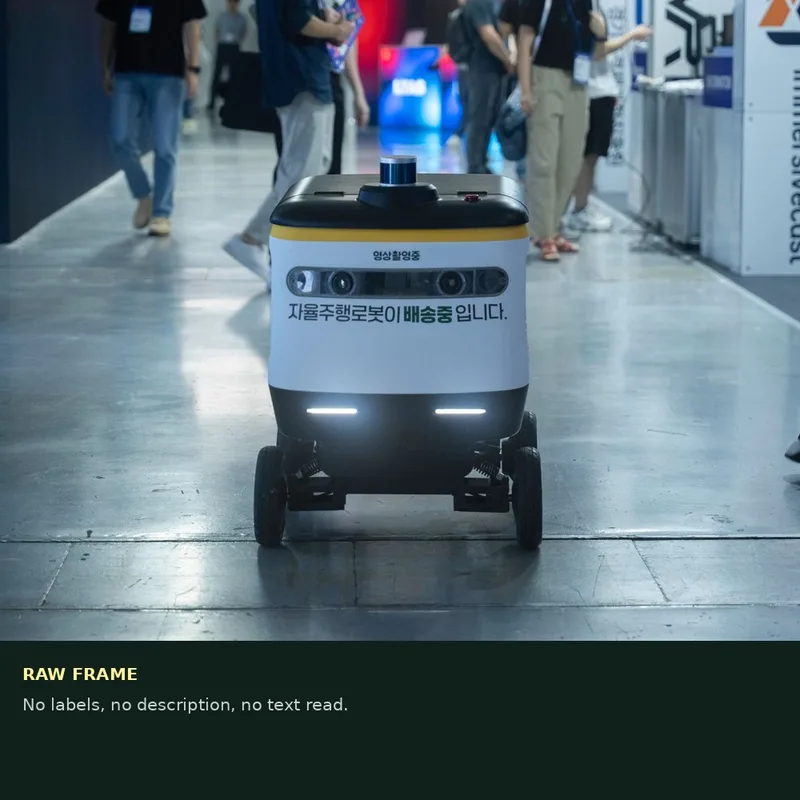
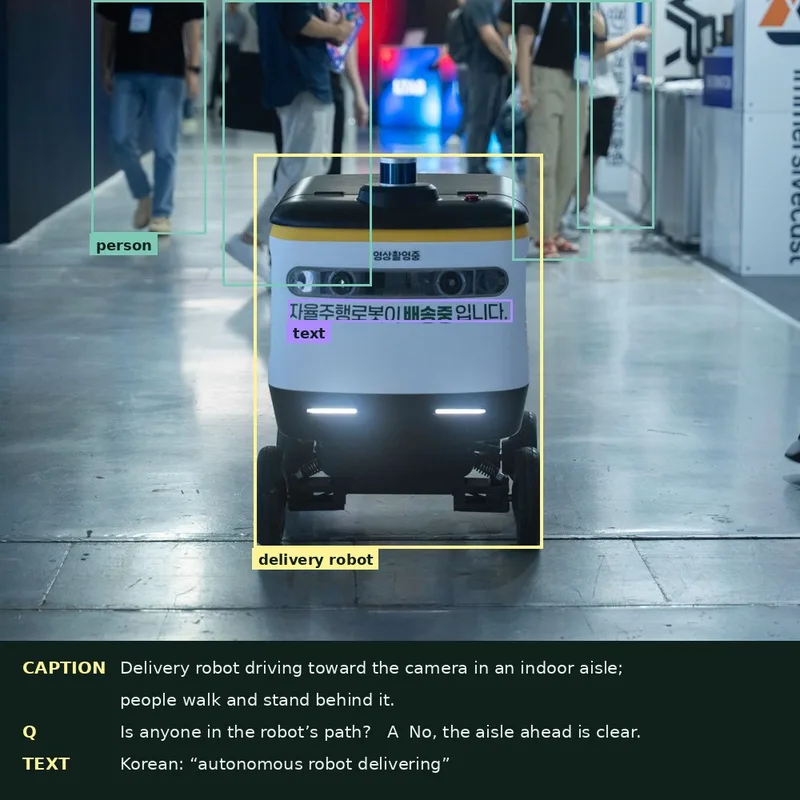
Data that links what a model sees with what it reads and hears, for models that work across images, video, text and sound.
- Image captioning & descriptions
- Video scene descriptions
- Visual question-and-answer pairs
- Image–text matching
- Audio–video alignment
- Multimodal data for robot navigation
- Custom task types designed around your model
Recently delivered for a fleet robotics company’s navigation models.
Quality & evaluation
Proof that your data and your model hold up.
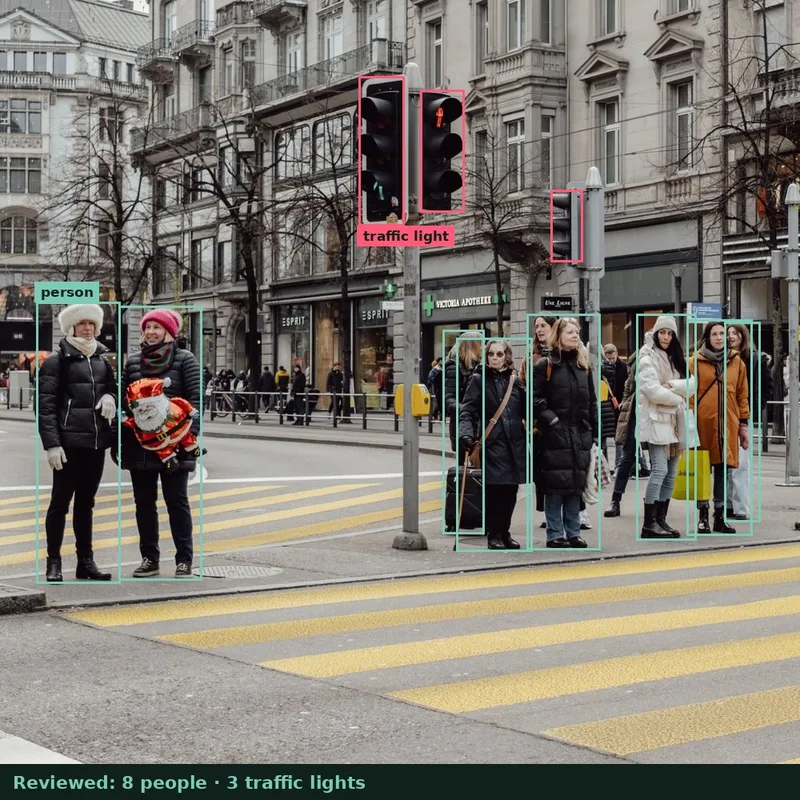
Data quality audits & QA
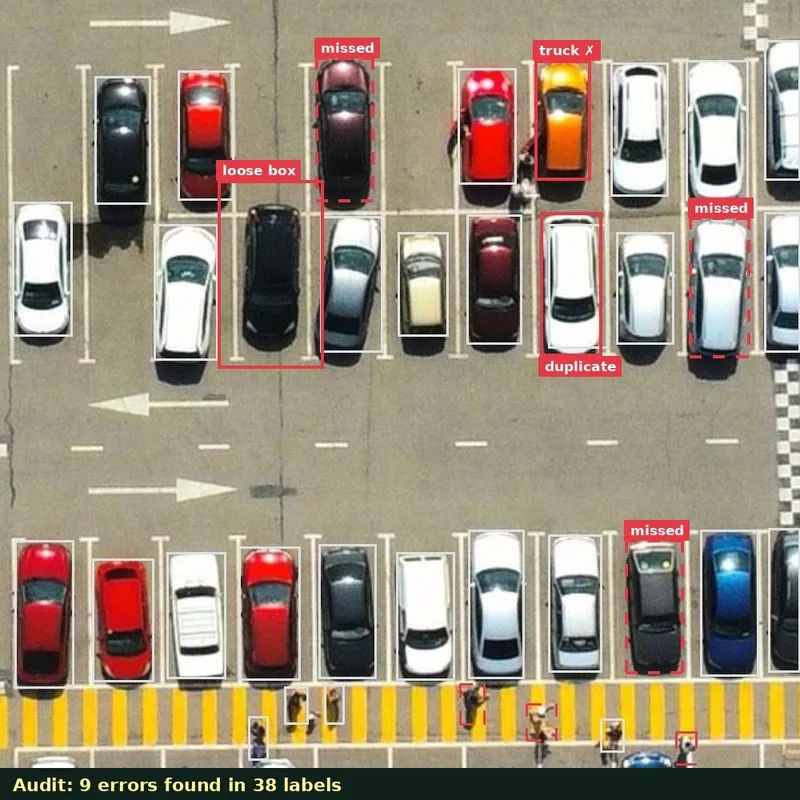
We find what is wrong in your dataset before it reaches training.
- Label error audits
- Guideline gap review
- Edge-case identification
- Agreement & accuracy reporting
- Correction and re-labelling
- Ongoing QA for live projects
Works on data labelled by anyone: your team, another vendor, or us.
Model output review
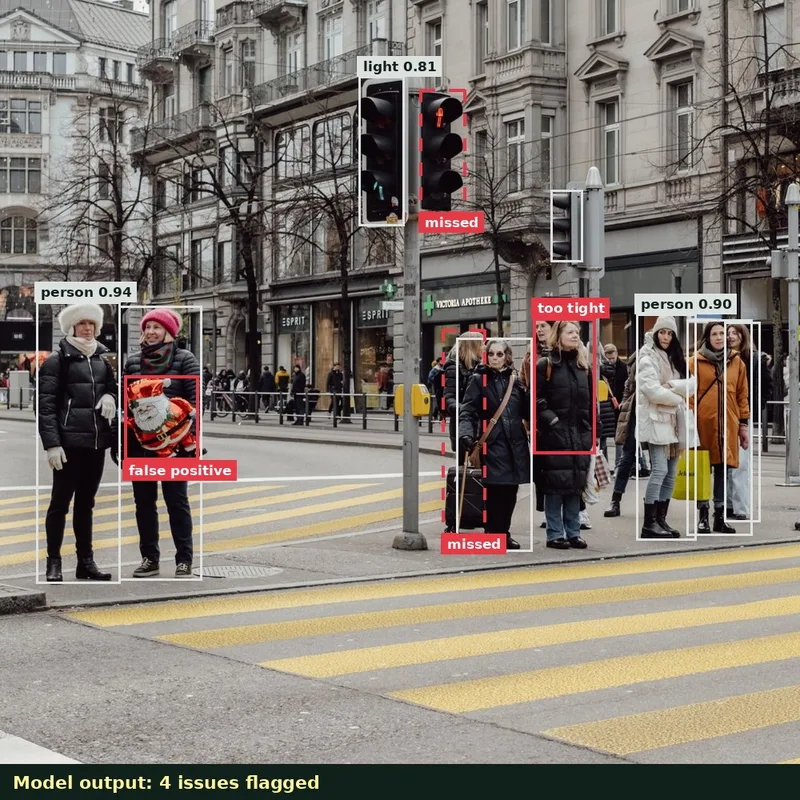
People check your model’s predictions, flag the misses and feed the hard cases back into training.
- Prediction verification
- False positive & negative flagging
- Edge-case collection
- Human-in-the-loop review
- Error analysis reports
Data operations
The work around the labels.
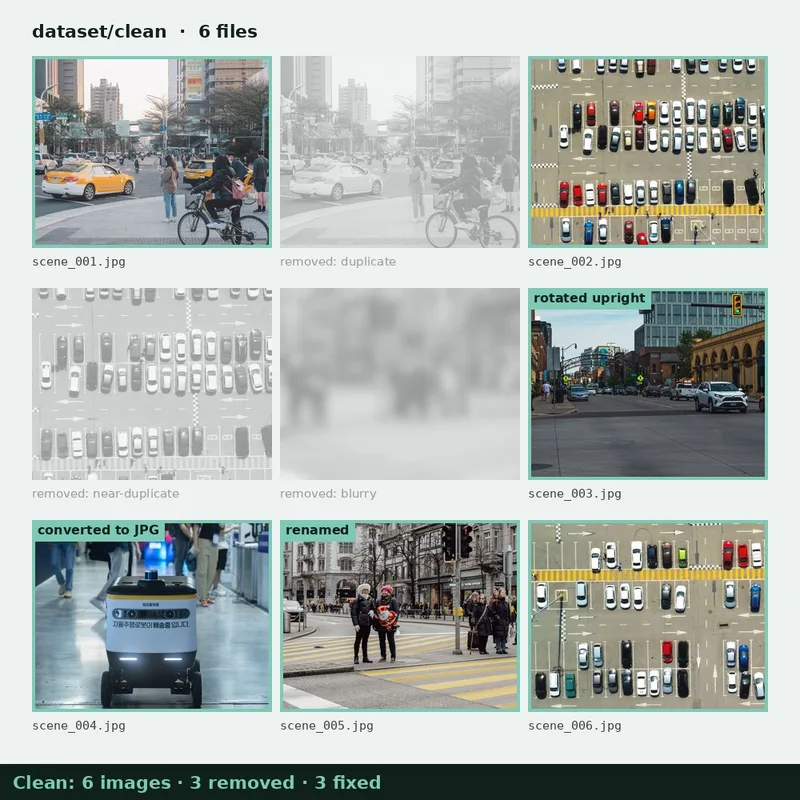
Data cleaning & processing
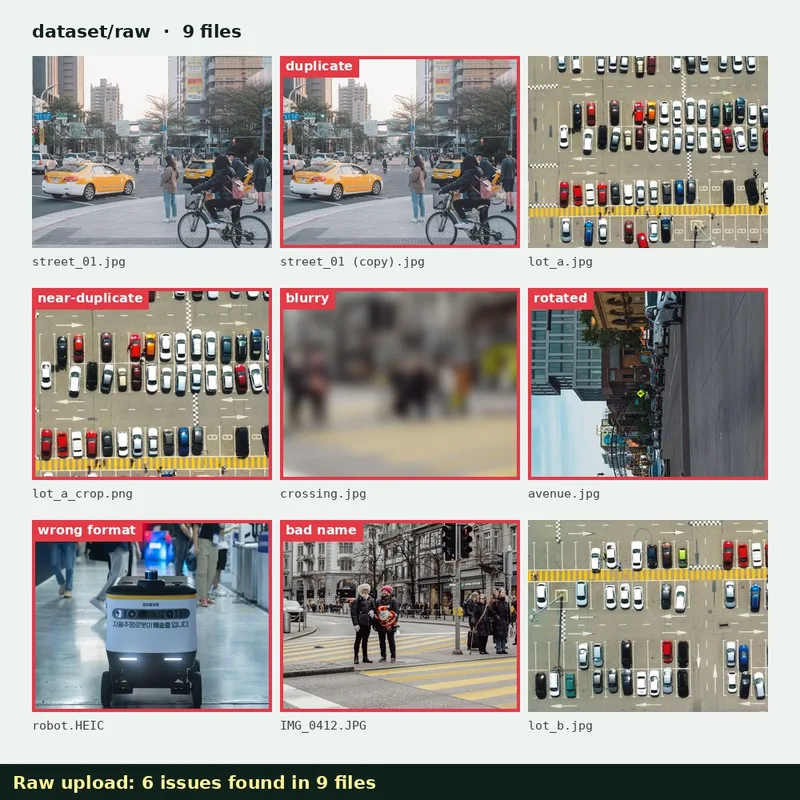
Raw data made training-ready: sorted, filtered, de-duplicated and delivered in the format your pipeline expects.
- Filtering & sorting
- De-duplication
- Format conversion
- Metadata tagging
- Dataset structuring
Content moderation
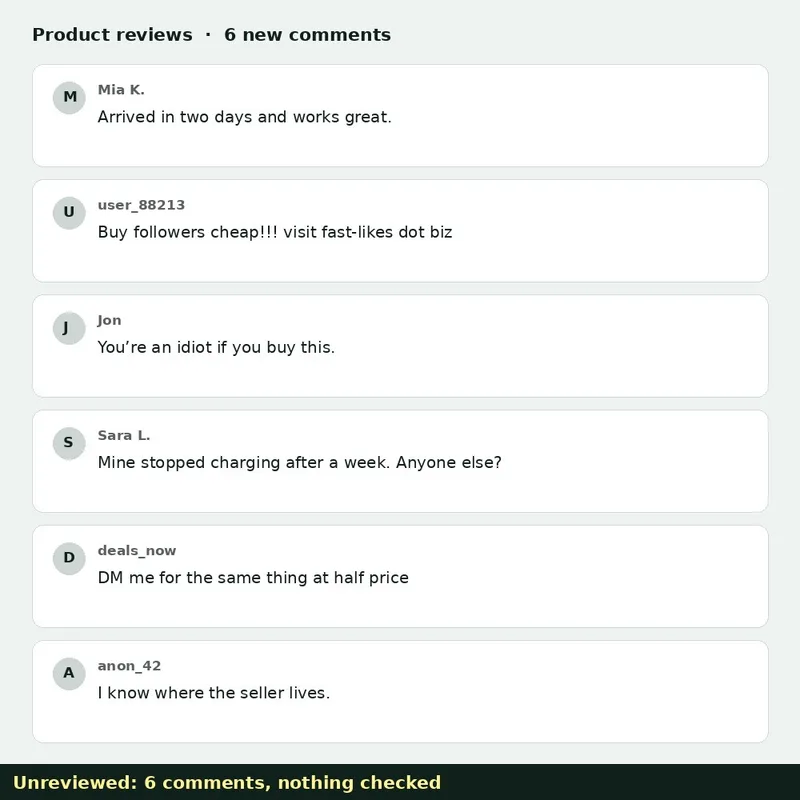
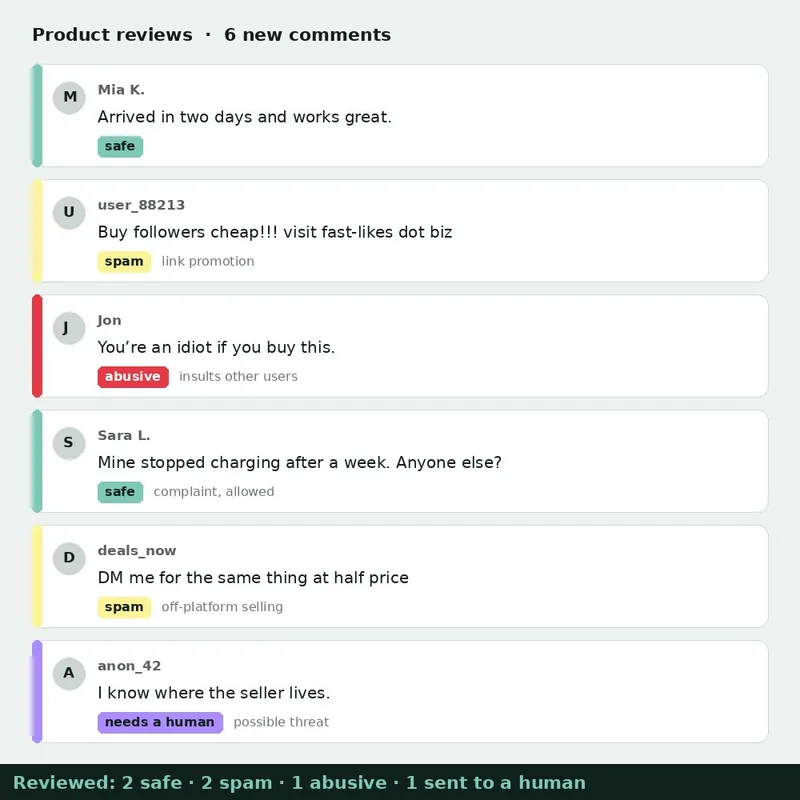
Trained reviewers who check images, video and text against your policies, and label data to train moderation models.
- Policy-based review
- Image & video moderation
- Text moderation
- Moderation training data
How we work with you
- 01
Free pilot
A sample batch on your own data, sized on a short call and delivered with a QA report.
- 02
Project
Fixed scope with per-asset pricing. Guideline design included.
- 03
Dedicated team
A named team lead and trained annotators working inside your workflow, with weekly reporting.
We work in your annotation platform or in-house tooling. No tooling yet? Use our own platform, built on CVAT and hosted in Europe, at no extra cost, with owner access to your project. We deliver in your format. How the platform is secured
Start with a free pilot batch
We agree the batch size on a short call. If the quality isn't there, you've lost nothing.